<?xml version="1.0" encoding="utf-8"?><feed xmlns="http://www.w3.org/2005/Atom" xml:lang="en-US"><generator uri="https://jekyllrb.com/" version="4.1.1">Jekyll</generator><link href="https://shlema.me/feed.xml" rel="self" type="application/atom+xml" /><link href="https://shlema.me/" rel="alternate" type="text/html" hreflang="en-US" /><updated>2026-04-13T12:54:41+02:00</updated><id>https://shlema.me/feed.xml</id><title type="html">Andrii Degeler</title><subtitle>Homepage</subtitle><author><name>Andrii Degeler</name><email>shlema@gmail.com</email></author><entry><title type="html">Tokenmaxxing technologists vs. AI-cautious journalists</title><link href="https://shlema.me/tokenmaxxing-vs-journalism/" rel="alternate" type="text/html" title="Tokenmaxxing technologists vs. AI-cautious journalists" /><published>2026-04-13T00:00:00+02:00</published><updated>2026-04-13T00:00:00+02:00</updated><id>https://shlema.me/tokenmaxxing-vs-journalism</id><content type="html" xml:base="https://shlema.me/tokenmaxxing-vs-journalism/"><![CDATA[<p>Found this data point recently: “AI-assisted stories accounted for nearly 20% of Fortune’s web traffic in the second half of 2025.” Even though “AI-assisted” is still a pretty vague definition, I can’t say I see a lot of data lying around on the exact impact of AI.</p>

<p>The number comes from <a href="https://www.wsj.com/business/media/an-ai-upheaval-is-coming-for-media-this-journalist-is-already-all-in-3511d951?mod=e2li">WSJ’s recent feature</a> on Fortune’s foray into AI journalism, spearheaded by Nick Lichtenberg. He’d published over 600 stories in about eight months — and most of the pieces are at least partially AI-generated, but always checked and edited by the author.</p>

<p>The piece also mentioned that “most of the roughly 60 journalists at Fortune aren’t doing their jobs the way Lichtenberg is,” which suggests that the “AI-assisted” stories are produced by a small number of people with significant involvement of one or more LLMs. In which case, 20% is a lot — and shows the potential of AI in journalism when used well.</p>

<p>The WSJ piece is also a rare case of a reasonably big publication showing how AI is used “in production.” I read often about both industries — and I’ve noticed a striking difference in how their representatives usually talk about generative AI.</p>

<p>In tech, you’ve got your “tokenmaxxing” — that is, competing on who spends more on AI usage — and executives shouting from the rooftops how much they’re employing AI every step of the way. In media, however, a lot of people tend to be significantly more careful in disclosing and discussing their usage of LLMs.</p>

<p>Harriet Meyer, who trains media people in AI, talked about the same thing in her <a href="https://www.linkedin.com/pulse/were-all-using-ai-can-we-just-say-so-harriet-meyer-h61ee/">excellent newsletter today</a>: hallucinations are real, and there are plenty of documented cases where AI screwed up journalistic output. But, as she puts it, “people can’t opt out, even if they want to. AI’s already in the spellchecker, the inbox, the search box, the transcription tool, and half the software their company already pays for.”</p>

<p>Of course, the journalistic AI tools need to improve across the board, from hallucination protection to copy and reasoning quality. Yet, the tools in existence can already provide enough support for a journalist in ideation, editing, and finding the best data.</p>

<p>Lichtenberg told WSJ that he’s seeing a “vibe shift” in journalists’ attitude towards AI, as well as that he’s been able to win people over by explaining his process and all the checks and balances involved.</p>

<p>If that’s indeed the case, we’re about to see how the two paths — those of the technologists and journalists — will inevitably converge; and it will be the journalists using more AI in their day-to-day work rather than the technologists using less of it.</p>]]></content><author><name>Andrii Degeler</name><email>shlema@gmail.com</email></author><summary type="html"><![CDATA[Found this data point recently: “AI-assisted stories accounted for nearly 20% of Fortune’s web traffic in the second half of 2025.” Even though “AI-assisted” is still a pretty vague definition, I can’t say I see a lot of data lying around on the exact impact of AI.]]></summary><media:thumbnail xmlns:media="http://search.yahoo.com/mrss/" url="https://shlema.me/assets/img/tokenmaxxing-journalism.jpg" /><media:content medium="image" url="https://shlema.me/assets/img/tokenmaxxing-journalism.jpg" xmlns:media="http://search.yahoo.com/mrss/" /></entry><entry><title type="html">Optimising ourselves for AI</title><link href="https://shlema.me/optimising-ourselves-for-AI/" rel="alternate" type="text/html" title="Optimising ourselves for AI" /><published>2026-04-08T00:00:00+02:00</published><updated>2026-04-08T00:00:00+02:00</updated><id>https://shlema.me/optimising-ourselves-for-AI</id><content type="html" xml:base="https://shlema.me/optimising-ourselves-for-AI/"><![CDATA[<p>An <a href="https://www.nytimes.com/2026/03/29/opinion/ai-claude-chatgpt-gemini-mcluhan.html">interesting point by Ezra Klein</a> on the NYT about one inevitable consequence of going all-in on AI and letting it to touch and ingest every aspect of your life:</p>

<div class="language-plaintext highlighter-rouge"><div class="highlight"><pre class="highlight"><code>The advantages of working atop an army of A.I. assistants and coders will compound over time, and to begin that process now is to launch yourself far ahead of your competition later. And so they are racing one another to fully integrate A.I. into their lives and into their companies. But that doesn’t just mean using A.I. It means making themselves legible to the A.I.
</code></pre></div></div>

<p>When taken too far, however, this process may result in “cognitive surrender,” when one’s own judgement is replaced by that of AI.</p>

<p>Together with the incessant sycophancy of many (most, really) AI tools and their tendency to reinforce things they think they know about you, this could lead to AI literally shaping a person rather than the other way around — and without due self-discipline, we we probably won’t like the result.</p>]]></content><author><name>Andrii Degeler</name><email>shlema@gmail.com</email></author><summary type="html"><![CDATA[An interesting point by Ezra Klein on the NYT about one inevitable consequence of going all-in on AI and letting it to touch and ingest every aspect of your life:]]></summary><media:thumbnail xmlns:media="http://search.yahoo.com/mrss/" url="https://shlema.me/assets/img/optimising-for-ai.jpg" /><media:content medium="image" url="https://shlema.me/assets/img/optimising-for-ai.jpg" xmlns:media="http://search.yahoo.com/mrss/" /></entry><entry><title type="html">OpenAI and TBPN — sure, but why?</title><link href="https://shlema.me/openai-tbpn-deal/" rel="alternate" type="text/html" title="OpenAI and TBPN — sure, but why?" /><published>2026-04-07T00:00:00+02:00</published><updated>2026-04-07T00:00:00+02:00</updated><id>https://shlema.me/openai-tbpn-deal</id><content type="html" xml:base="https://shlema.me/openai-tbpn-deal/"><![CDATA[<p>To quickly weigh in about <a href="https://www.wsj.com/cmo-today/openai-buys-tech-industry-talk-show-tbpn-484c01c5">OpenAI having acquired TBPN</a> — a few days after the news broke, I’m still not sure why both sides would’ve wanted this deal to happen.</p>

<p>Normally, an acquisition like this would make obvious sense for at least one of the parties involved. But that’s not the case here, or at least I don’t see it somehow.</p>

<p>What’d OpenAI want from a team of 11 people? According to WSJ (and many other sources) this is the plan:</p>

<blockquote>
  <p>TBPN will report to Chris Lehane, OpenAI’s chief global affairs officer, and will <mark>help with company communications and marketing</mark> outside of the show.</p>
</blockquote>

<p>What do you mean, “outside of the show”? It’s a daily three-hour livestream, there’s no such thing as “outside of the show”! I really don’t see how the team would be able to contribute meaningfully to anything else than TBPN itself.</p>

<p>And then, why would the TBPN folks sell? They say the revenue is growing, and the company profitable, meaning they’ve got a reasonably clear path towards building a very viable media business. Selling to OpenAI — even for the reported $100 million - inevitably caps both the financial gains and, likely, the audience and credibility.</p>

<p>TBPN is by definition not a journalistic outlet, it’s positioned as an uncritical warm bath show — but it was still an independent one, and this was one of the reasons they were able to book such a wide range of high-profile guests.</p>

<p>No matter how much editorial independence they will end up with under OpenAI, I’m just not sure TBPN will ever be seen the same way, and whether, for instance, representatives of OpenAI’s competition would want to come come on the show.</p>

<p>On the other hand, <a href="https://x.com/chaykak/status/2039775266709410226">Kyle Chayka on X had a good point</a>:</p>

<blockquote>
  <p>“that said… media brands should get the bag when they can because you can always start over, the brand will die so fast if it sucks and you can always start a new one…”</p>
</blockquote>

<p>So, it’s definitely a win for the TBPN team — but I’m not quite sure OpenAI will be able to get quite the bang for their buck they expect. Unless, of course, their reasoning is entirely different, in which case I’m very curious to see it all play out.</p>]]></content><author><name>Andrii Degeler</name><email>shlema@gmail.com</email></author><summary type="html"><![CDATA[To quickly weigh in about OpenAI having acquired TBPN — a few days after the news broke, I’m still not sure why both sides would’ve wanted this deal to happen.]]></summary><media:thumbnail xmlns:media="http://search.yahoo.com/mrss/" url="https://shlema.me/" /><media:content medium="image" url="https://shlema.me/" xmlns:media="http://search.yahoo.com/mrss/" /></entry><entry><title type="html">GenAI as the ultimate platform, or a dystopian scenario for media</title><link href="https://shlema.me/the-ultimate-platform/" rel="alternate" type="text/html" title="GenAI as the ultimate platform, or a dystopian scenario for media" /><published>2025-01-27T00:00:00+01:00</published><updated>2025-01-27T00:00:00+01:00</updated><id>https://shlema.me/the-ultimate-platform</id><content type="html" xml:base="https://shlema.me/the-ultimate-platform/"><![CDATA[<p>Here’s an interesting thing to think about: what happens if generative AI platforms become the main interface for humans to access information? And more narrowly, what would it mean for media and journalism?</p>

<p>I already mentioned <a href="https://www.bloomberg.com/news/articles/2025-01-10/8-ways-ai-will-transform-journalism">the essay</a> by Bloomberg News’ editor-in-chief John Micklethwait on AI and journalism the other day. Here’s a passage from the piece:</p>

<div class="language-plaintext highlighter-rouge"><div class="highlight"><pre class="highlight"><code>“[…] reporting will still have enormous value. […] you need reporting. An AI summary is only as good as the story it is based on. And getting the stories is where the humans still matter.”
</code></pre></div></div>

<p>I wholeheartedly agree with this notion, there’s really no way around it. However, I’m not sure it necessarily means that the future of media and journalism as we know them now is secured.</p>

<p>Here’s the thing. If you look at a general-purpose LLM platform from its developer’s standpoint, you can say that the website of any media publication whose data is being ingested into the LLM is just an intermediary step between the user and the information they want to access (provided by a reporter in most cases). So, why not cut out the middleman by getting journalists to contribute straight into the model?</p>

<p>In fact, this process seems to have already started. I’m aware of multiple companies, in Europe and elsewhere, that are hiring specialist writers — including journalists — to write copy that will never see the light of day. Its sole purpose is to be ‘training fodder’ for a proprietary LLM.</p>

<p>Dystopian as it may sound, I really don’t see a lot of barriers for that to happen, outside of the technical limitations related to hallucinations and incremental training of LLMs (both of which could be solved at least partially with a combination RAG and fine-tuning, as far as I understand). Of course <a href="https://en.wikipedia.org/wiki/AI_slop">AI slop</a> spat out by the model will remain just that — but the concept could become quite attractive if implemented at scale; it can also be a way for the platform to differentiate on the market.</p>

<p>Imagine an LLM company that both scrapes existing media outlets’ websites aggressively (including through partnership agreements like the ones between <a href="https://aboutus.ft.com/press_release/openai">OpenAI and Financial Times</a> or <a href="https://www.afp.com/en/agency/inside-afp/press-release/afp-and-mistral-ai-announce-global-partnership-enhance-ai-responses">Mistral AI and AFP</a>) and employs its own reporters to feed the model. It could have human-curated and AI-generated “front page,” and build all sorts of digests, listicles, and news overviews for each reader individually. I wouldn’t be surprised if enough people from less picky audience segments were happy to flock to such publications.</p>

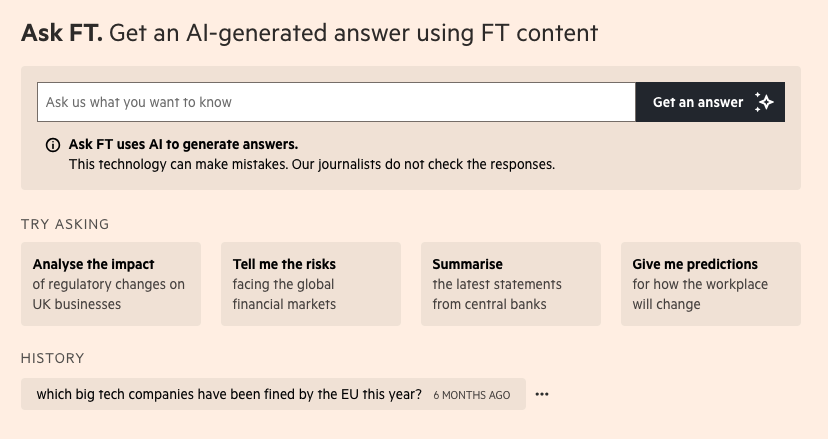
<p>The logical next step from there would be for media outlets to try and protect themselves from becoming eaten alive by AI companies. Firstly, they’d likely need to train their own models on their own data and offer them through a chat interface to stay competitive. And once again, this seems to be happening already — for example, Financial Times has <a href="https://ask.ft.com">ask.ft.com</a>, which does exactly that.</p>

<p><img src="/assets/img/askft.png" caption="" /></p>

<p>Secondly, traditional media outlets would need to protect their original reporting from being ingested in competing models. And as long as LLMs can’t be successfully trained on data generated by other LLMs, the best way to do that would be to never publish said reporting in the first place — which, again, leaves us with GenAI as the ‘ultimate platform’ for information access.</p>

<p>I wouldn’t go as far as calling this a prediction, but this scenario sounds much less impossible than it would’ve just a couple of years ago. And that’s properly terrifying.</p>

<p><em>Since there’s no comment section here for the time being, feel free to <a href="https://www.linkedin.com/posts/shlema_heres-an-interesting-thing-to-think-about-activity-7289564905672777729-NEBc">join the conversation on LinkedIn</a>.</em></p>]]></content><author><name>Andrii Degeler</name><email>shlema@gmail.com</email></author><summary type="html"><![CDATA[Here’s an interesting thing to think about: what happens if generative AI platforms become the main interface for humans to access information? And more narrowly, what would it mean for media and journalism?]]></summary><media:thumbnail xmlns:media="http://search.yahoo.com/mrss/" url="https://shlema.me/" /><media:content medium="image" url="https://shlema.me/" xmlns:media="http://search.yahoo.com/mrss/" /></entry><entry><title type="html">On media business models, old and new</title><link href="https://shlema.me/media-business-models/" rel="alternate" type="text/html" title="On media business models, old and new" /><published>2025-01-22T00:00:00+01:00</published><updated>2025-01-22T00:00:00+01:00</updated><id>https://shlema.me/media-business-models</id><content type="html" xml:base="https://shlema.me/media-business-models/"><![CDATA[<p>Bloomberg News’ editor-in-chief John Micklethwait <a href="https://www.bloomberg.com/news/articles/2025-01-10/8-ways-ai-will-transform-journalism">wrote a great piece</a> recently with a series of predictions of the main changes AI will bring to journalism. I think he actually missed one important thing that’s rather dystopian — but I’ll try to write a longer post about it tomorrow.</p>

<p>For now, I was thinking about a point he made at the beginning as he was listing the historical reasons of why the media market is the way it is today:</p>

<div class="language-plaintext highlighter-rouge"><div class="highlight"><pre class="highlight"><code>Far too many quality media brands fell for the tech-rhetoric that “legacy media” was dead and that content should be free. Soon they were stuck in a vicious circle of chasing clicks, cutting costs and gradually handing over their business to the tech giants.

But eventually sense prevailed, people started to charge for journalism and legacy media began to recover. The New York Times, which had only 500,000 digital subscribers when Mark Thompson arrived in 2012 and focused the Grey Lady on selling subscriptions, now has more than 10 million paying customers. The “content is free” sirens who lured so many great names onto the rocks have shut up; the new challengers like The Information, Puck and (despite its name) The Free Press make sure people pay sooner or later.
</code></pre></div></div>

<p>As I was thinking why the legacy media publications went for the “free content” model, I realised something I didn’t quite think about before: that is actually something they had been conditioned to believe since long before they made the shift.</p>

<p>Correct me if I’m wrong, but had it not been the case for most if not all publications back in the 2000s that the revenue from subscriptions and newsstand sales was almost negligible compared to that from classified and display ads? I guess you could see that part of the income as a way to cover the printing costs.</p>

<p>And if that’s the case, then it wasn’t really such a big paradigm shift for legacy media moving into the online realm to dismiss the idea of introducing digital subscriptions right off the bat.</p>

<p>Conversely, it is only now that we’re seemingly entering a new era of media monetisation that prioritises subscription revenue, while in the past 15-20 years most publications have been trying, to a varying degree of success, to replicate the old model.</p>

<p>(It could seem an obvious thing — but I’ve somehow been considering the rise of subscriptions as a “return to the old model,” which it actually isn’t — at least not from the business standpoint.)</p>

<p><em>Since there’s no comment section here for the time being, feel free to <a href="https://www.linkedin.com/posts/shlema_bloomberg-news-editor-in-chief-john-micklethwait-activity-7287867208305639424-o4kJ?utm_source=share&amp;utm_medium=member_desktop">join the conversatoin on LinkedIn</a>.</em></p>]]></content><author><name>Andrii Degeler</name><email>shlema@gmail.com</email></author><summary type="html"><![CDATA[Bloomberg News’ editor-in-chief John Micklethwait wrote a great piece recently with a series of predictions of the main changes AI will bring to journalism. I think he actually missed one important thing that’s rather dystopian — but I’ll try to write a longer post about it tomorrow.]]></summary><media:thumbnail xmlns:media="http://search.yahoo.com/mrss/" url="https://shlema.me/" /><media:content medium="image" url="https://shlema.me/" xmlns:media="http://search.yahoo.com/mrss/" /></entry><entry><title type="html">Jonathan Coulton and the challenge of finding new good music</title><link href="https://shlema.me/jonathan-coulton/" rel="alternate" type="text/html" title="Jonathan Coulton and the challenge of finding new good music" /><published>2024-12-31T00:00:00+01:00</published><updated>2024-12-31T00:00:00+01:00</updated><id>https://shlema.me/jonathan-coulton</id><content type="html" xml:base="https://shlema.me/jonathan-coulton/"><![CDATA[<p>I only recently found out that the Portal credits song (<em>Still Alive</em>) and the old-but-funny <em>Re: Your Brains</em> are actually written by the same person, that’s <a href="https://www.jonathancoulton.com/">Jonathan Coulton</a>.</p>

<p>Here, do give them a listen if you haven’t (the former is admittedly much more funny if you’ve played Portal):</p>

<iframe width="560" height="315" src="https://www.youtube.com/embed/Y6ljFaKRTrI?si=czu52RA3KCrkcDe0" title="YouTube video player" frameborder="0" allow="accelerometer; autoplay; clipboard-write; encrypted-media; gyroscope; picture-in-picture; web-share" referrerpolicy="strict-origin-when-cross-origin" allowfullscreen=""></iframe>

<iframe width="560" height="315" src="https://www.youtube.com/embed/S6vnM9I7HIo?si=rbYuG8Bcafqg5aSW" title="YouTube video player" frameborder="0" allow="accelerometer; autoplay; clipboard-write; encrypted-media; gyroscope; picture-in-picture; web-share" referrerpolicy="strict-origin-when-cross-origin" allowfullscreen=""></iframe>

<p>The good news is that Coulton’s got a lot more great music to rummage through, which is what I’m planning to be doing over the next few weeks.</p>

<p>On that note, it’s been talked about a bunch but I’m experiencing it as well: the older you get, the harder it becomes to discover new music I’d really like. I used to add new songs to my ‘master playlist’ (on Spotify, and now on Google Music) multiple times a week — and now it hardly happens once a month.</p>

<p>It also doesn’t help that the recommendation algorithms seem to be at a loss with the mess that is the music I play daily. Between a lot of instrumental music and movie and videogame soundtracks I play in the background when I work, the actual music I like to listen to, and a bunch of Dutch songs for kids (Juf Roos FTW), I’m not surprised most of the suggestions I get in the music apps make no sense.</p>

<p>That’s all to say, check out Jonathan Coulton if that sounds like your thing, and feel free to suggest what I should listen to in any way known to you.</p>]]></content><author><name>Andrii Degeler</name><email>shlema@gmail.com</email></author><summary type="html"><![CDATA[I only recently found out that the Portal credits song (Still Alive) and the old-but-funny Re: Your Brains are actually written by the same person, that’s Jonathan Coulton.]]></summary><media:thumbnail xmlns:media="http://search.yahoo.com/mrss/" url="https://shlema.me/" /><media:content medium="image" url="https://shlema.me/" xmlns:media="http://search.yahoo.com/mrss/" /></entry><entry><title type="html">Microsoft is (kind of) blaming the EU after the CrowdStrike disaster</title><link href="https://shlema.me/eu-crowdstrike/" rel="alternate" type="text/html" title="Microsoft is (kind of) blaming the EU after the CrowdStrike disaster" /><published>2024-07-26T00:00:00+02:00</published><updated>2024-07-26T00:00:00+02:00</updated><id>https://shlema.me/eu-crowdstrike</id><content type="html" xml:base="https://shlema.me/eu-crowdstrike/"><![CDATA[<p><em>[This post if part of our weekly <a href="https://thenextweb.com/newsletters">TNW Newsletter</a> — do subscribe if you haven’t yet!]</em></p>

<p>Last week, it felt like entire countries and industries came to a grinding halt due to an update of the CrowdStrike software package that caused 8.5 million Windows PCs across the world to enter into the infamous Blue Screen of Death. With all kinds of companies having experienced lengthy outages (and many of them are still suffering from issues), the situation doesn’t look good for CrowdStrike or for Microsoft, even though it wasn’t the direct fault of the latter.</p>

<p>CrowdStrike, the Texas-based security software provider targeting big businesses as its main customer base, was quick to admit its mistake and take full responsibility for the catastrophic update. The company’s shares plunged by some 25% on Friday as its clients struggled to apply fixes that required physically accessing every affected PC.</p>

<p>Microsoft, on the other hand, engaged in a low-key blaming game, as it remarked offhandedly that it was the EU’s decision on a complaint from 2009 that kept it from restricting access to Windows’ kernel for third-party apps. Numerous media outlets around the world dutifully ran the story with scathing headlines mocking Brussels’ stance when it comes to regulating Big Tech.</p>

<p>While Europe does tend to pay a lot of attention to antitrust and privacy issues when it comes to technology companies, the critique implied by Microsoft rings hollow.</p>

<p>If anything, the CrowdStrike debacle actually demonstrates the strength of the European approach. What we saw is that thanks to that 15-year-old complaint, thousands of businesses were given the opportunity to choose which security software to run on their 8.5 million computers — and ended up choosing a non-Microsoft solution, which suited them better.</p>

<p>That’s the entire idea behind this kind of regulation, isn’t it?</p>]]></content><author><name>Andrii Degeler</name><email>shlema@gmail.com</email></author><summary type="html"><![CDATA[[This post if part of our weekly TNW Newsletter — do subscribe if you haven’t yet!]]]></summary><media:thumbnail xmlns:media="http://search.yahoo.com/mrss/" url="https://shlema.me/assets/img/eu-crowdstrike-newsletter.jpg" /><media:content medium="image" url="https://shlema.me/assets/img/eu-crowdstrike-newsletter.jpg" xmlns:media="http://search.yahoo.com/mrss/" /></entry><entry><title type="html">Pirate Summit, one last time</title><link href="https://shlema.me/pirate-summit/" rel="alternate" type="text/html" title="Pirate Summit, one last time" /><published>2023-06-29T00:00:00+02:00</published><updated>2023-06-29T00:00:00+02:00</updated><id>https://shlema.me/pirate-summit</id><content type="html" xml:base="https://shlema.me/pirate-summit/"><![CDATA[<p>Seven years ago, in 2016, I entered the scrapeyard-turned-event venue that’s Odonien for the first time to attend that year’s Pirate Summit. To be entirely honest, I remember very little from the event, and I’ve only got a handful of photos of Fred Destin and the Burn on my phone to refresh my memory.</p>

<div class="carousel__holder">
    <div id="carousel0" class="carousel">
        
          <input class="carousel__activator" type="radio" name="carousel0" id="0a" checked="checked" />
        
          <input class="carousel__activator" type="radio" name="carousel0" id="0b" />


          <div class="carousel__controls">
              <label class="carousel__control carousel__control--backward" for="0b"></label>
              <label class="carousel__control carousel__control--forward" for="0b"></label>
          </div>


          <div class="carousel__controls">
              <label class="carousel__control carousel__control--backward" for="0a"></label>
              <label class="carousel__control carousel__control--forward" for="0a"></label>
          </div>
        
        <div class="carousel__track">
          <ul>
            
            <li class="carousel__slide" style="background-image: url('/assets/img/pirate-2016-01.jpg');"></li>
            
            <li class="carousel__slide" style="background-image: url('/assets/img/pirate-2016-02.jpg');"></li>
            
          </ul>
        </div>
        <div class="carousel__indicators">
            
              <label class="carousel__indicator" for="0a"></label>
            
              <label class="carousel__indicator" for="0b"></label>
            
        </div>
    </div>
</div>

<style>
.carousel__holder {width: 100%; position: relative; padding-bottom: 50%; margin: 1rem 0 1rem;}
.carousel {
  height: 100%;
  width: 100%;
  overflow: hidden;
  text-align: center;
  position: absolute;
  padding: 0;
}
.carousel__controls,
.carousel__activator {
  display: none;
}

.carousel__activator:nth-of-type(1):checked ~ .carousel__track {
  -webkit-transform: translateX(-000%);
          transform: translateX(-000%);
}
.carousel__activator:nth-of-type(1):checked ~ .carousel__slide:nth-of-type(1) {
  transition: opacity 0.5s, -webkit-transform 0.5s;
  transition: opacity 0.5s, transform 0.5s;
  transition: opacity 0.5s, transform 0.5s, -webkit-transform 0.5s;
  top: 0;
  left: 0;
  right: 0;
  opacity: 1;
  -webkit-transform: scale(1);
          transform: scale(1);
}
.carousel__activator:nth-of-type(1):checked ~ .carousel__controls:nth-of-type(1) {
  display: block;
  opacity: 1;
}
.carousel__activator:nth-of-type(1):checked ~ .carousel__indicators .carousel__indicator:nth-of-type(1) {
  opacity: 1;
}

.carousel__activator:nth-of-type(2):checked ~ .carousel__track {
  -webkit-transform: translateX(-100%);
          transform: translateX(-100%);
}
.carousel__activator:nth-of-type(2):checked ~ .carousel__slide:nth-of-type(2) {
  transition: opacity 0.5s, -webkit-transform 0.5s;
  transition: opacity 0.5s, transform 0.5s;
  transition: opacity 0.5s, transform 0.5s, -webkit-transform 0.5s;
  top: 0;
  left: 0;
  right: 0;
  opacity: 1;
  -webkit-transform: scale(1);
          transform: scale(1);
}
.carousel__activator:nth-of-type(2):checked ~ .carousel__controls:nth-of-type(2) {
  display: block;
  opacity: 1;
}
.carousel__activator:nth-of-type(2):checked ~ .carousel__indicators .carousel__indicator:nth-of-type(2) {
  opacity: 1;
}


.carousel__control {
  height: 30px;
  width: 30px;
  margin-top: -15px;
  top: 50%;
  position: absolute;
  display: block;
  cursor: pointer;
  border-width: 5px 5px 0 0;
  border-style: solid;
  border-color: #fafafa;
  opacity: 0.35;
  opacity: 1;
  outline: 0;
  z-index: 3;
}
.carousel__control:hover {
  opacity: 1;
}
.carousel__control--backward {
  left: 20px;
  -webkit-transform: rotate(-135deg);
          transform: rotate(-135deg);
}
.carousel__control--forward {
  right: 20px;
  -webkit-transform: rotate(45deg);
          transform: rotate(45deg);
}
.carousel__indicators {
  position: absolute;
  bottom: 20px;
  width: 100%;
  text-align: center;
}
.carousel__indicator {
  height: 15px;
  width: 15px;
  border-radius: 100%;
  display: inline-block;
  z-index: 2;
  cursor: pointer;
  opacity: 0.35;
  margin: 0 2.5px 0 2.5px;
}
.carousel__indicator:hover {
  opacity: 0.75;
}
.carousel__track {
  position: absolute;
  top: 0;
  right: 0;
  bottom: 0;
  left: 0;
  padding: 0;
  margin: 0;
  transition: -webkit-transform 0.5s ease 0s;
  transition: transform 0.5s ease 0s;
  transition: transform 0.5s ease 0s, -webkit-transform 0.5s ease 0s;
}
.carousel__track .carousel__slide {
  display: block;
  top: 0;
  left: 0;
  right: 0;
  opacity: 1;
}

.carousel__track .carousel__slide:nth-of-type(1) {
  -webkit-transform: translateX(000%);
          transform: translateX(000%);
}

.carousel__track .carousel__slide:nth-of-type(2) {
  -webkit-transform: translateX(100%);
          transform: translateX(100%);
}


.carousel--scale .carousel__slide {
  -webkit-transform: scale(0);
          transform: scale(0);
}
.carousel__slide {
  height: 100%;
  position: absolute;
  opacity: 0;
  overflow: hidden;
}
.carousel__slide .overlay {height: 100%;}
.carousel--thumb .carousel__indicator {
  height: 30px;
  width: 30px;
}
.carousel__indicator {
  background-color: #fafafa;
}

.carousel__slide:nth-of-type(1),
.carousel--thumb .carousel__indicators .carousel__indicator:nth-of-type(1) {
  background-size: cover;
  background-position: center;
}

.carousel__slide:nth-of-type(2),
.carousel--thumb .carousel__indicators .carousel__indicator:nth-of-type(2) {
  background-size: cover;
  background-position: center;
}

</style>

<script>
  function isVisible(el) {
        while (el) {
            if (el === document) {
                return true;
            }

            var $style = window.getComputedStyle(el, null);

            if (!el) {
                return false;
            } else if (!$style) {
                return false;
            } else if ($style.display =<mark> 'none') {
                return false;
            } else if ($style.visibility </mark>= 'hidden') {
                return false;
            } else if (+$style.opacity =<mark> 0) {
                return false;
            } else if (($style.display </mark>= 'block' || $style.display =<mark> 'inline-block') &&
                $style.height </mark>= '0px' && $style.overflow =<mark> 'hidden') {
                return false;
            } else {
                return $style.position </mark>= 'fixed' || isVisible(el.parentNode);
            }
        }
  }
  
  setInterval(function(){
    var j=0;
    var elements = document.querySelectorAll('#carousel0 .carousel__control--forward');
    for(i=(elements.length - 1);i>-1;i--) {
      if(isVisible(elements[i])) j=i;
    }
    elements[j].click();
  },10000);
  
</script>

<p>I must’ve liked what I saw in 2016 though, because I went back next year. And the year after, and the year after that — without missing a Pirate Summit ever since, up until this year’s Last Burn.</p>

<p>The European tech ecosystem has given birth to a great many of different events, including our own vibrant and festival-spirited TNW Conference in Amsterdam, the gargantuan Web Summit in Lisbon, and a whole bunch of smaller gatherings across the continent.</p>

<p>But I don’t think any of those events can easily replace Pirate Summit. Over the years, this seemingly scrappy, unpolished, raw gathering started to feel like home for a large group of European founders, investors, ecosystem builders, and journalists. But this June, we came to Odonien for the last time, and now Pirate Summit is no more.</p>

<p>As I was sitting on the hopelessly late train back to Amsterdam from Cologne last week, I was thinking about the importance of these small community-focused events for the ecosystem. It’s vital to have a space where unconference-style ‘campfire discussions’ of 10-20 people are given a prominent place in the agenda. Makes much more immediate sense than serious-looking round tables full of suited men at European institutions, if you ask me.</p>

<p>I hope we’ll find (or create) a new space that will — at least partially — replace this event. I, for one, am happy to help with any effort in that direction.</p>

<p>But for now, so long, Pirate Summit, and thanks for all the great memories.</p>

<p><img src="/assets/img/pirate-summit-reality.jpg" caption="" /></p>]]></content><author><name>Andrii Degeler</name><email>shlema@gmail.com</email></author><summary type="html"><![CDATA[Seven years ago, in 2016, I entered the scrapeyard-turned-event venue that’s Odonien for the first time to attend that year’s Pirate Summit. To be entirely honest, I remember very little from the event, and I’ve only got a handful of photos of Fred Destin and the Burn on my phone to refresh my memory.]]></summary><media:thumbnail xmlns:media="http://search.yahoo.com/mrss/" url="https://shlema.me/assets/img/pirate-2016-03.jpg" /><media:content medium="image" url="https://shlema.me/assets/img/pirate-2016-03.jpg" xmlns:media="http://search.yahoo.com/mrss/" /></entry><entry><title type="html">Can (and should) you actually record a podcast interview on Zoom?</title><link href="https://shlema.me/can-you-record-a-podcast-on-zoom/" rel="alternate" type="text/html" title="Can (and should) you actually record a podcast interview on Zoom?" /><published>2021-11-19T00:00:00+01:00</published><updated>2021-11-19T00:00:00+01:00</updated><id>https://shlema.me/can-you-record-a-podcast-on-zoom</id><content type="html" xml:base="https://shlema.me/can-you-record-a-podcast-on-zoom/"><![CDATA[<p>When I first took over the Tech.eu Podcast in 2018, one of the first decisions I made was that I’d only record interviews online in absolutely exceptional circumstances. Almost of my interviews from that and next year had been recorded in person, and there’s a whole bunch of reasons for that.</p>

<p>First of all, when I interview someone in person, I can control the audio quality. I’ve got my set of trusted recording gear, I always monitor the audio as I go, and I know exactly what to expect when I open the results on my computers. (Speaking of that — should I run a gear post later to talk about the stuff I use for recording at home and on the ground?)</p>

<p>Second, quality of the conversation tends to be higher when you’re sitting across the table from your guest. Maybe one day we’ll get so used to talking to our screens that it won’t be an issue anymore, but for now, the conversation flow of an in-person interview tends to be better than an online one is most cases. I’ve also noticed that when interviewed in person, people tend to add less fluff to their answers and be more straight-to-the-point.</p>

<p>So, with all that in mind, I wasn’t keen on recording online at all.</p>

<p>Then along came the pandemic, and my commitment to in-person interviews obviously went out the window. I’d done my homework back then and have been using purpose-made podcast recording platforms (first <a href="https://zencastr.com/">Zencastr</a>, then <a href="https://squadcast.fm/">Squadcast</a>), and didn’t really consider Zoom as an alternative.</p>

<p>However, a few months ago someone asked me to look into the best way to set up a podcast recording on Zoom (that was the only option), and I was surprised to see a bunch of interesting settings that promised to significantly improve its audio recording quality. I thought I should investigate it later just out of curiosity, and happily forgot about it, of course.</p>

<p>Now that I have a bit of spare time after <a href="https://shlema.me/leaving-tech-eu/">leaving Tech.eu</a>, I wanted to take a look and listen at whether Zoom could actually be a viable option to record a podcast interview.</p>

<p>Before moving on to testing this, I’m going to apply the following settings on Zoom:</p>

<ul>
  <li>Audio → Automatically adjust microphone volume: <strong>False</strong> (unchecked)</li>
  <li>Audio → Suppress background noise: <strong>Low</strong></li>
  <li>Audio → Music and Professional Audio → 
    <ul>
      <li>Show in-meeting option to enable “Original sound”: <strong>True</strong> (checked)</li>
      <li>High-fidelity music mode: <strong>True</strong> (checked)</li>
      <li>Echo cancellation: <strong>False</strong> (unchecked)</li>
      <li>Stereo audio: <strong>False</strong> (unchecked)</li>
    </ul>
  </li>
  <li>Recording → Record a separate audio file for each participant: <strong>True</strong> (checked)</li>
</ul>

<p>That seems to be it. If you know any other settings I should be checking, let me know in the comments section.</p>

<p>As far as I understand, Zoom still wouldn’t do what podcast recording services are doing, that is record each participant locally and upload the result to the cloud. This means that your interviewee would need to set all the same settings on their side, turn Original Sound on (!), and start recording on their side as well. Sounds like a bit of a hassle, but it still should be easier than asking people to record in a separate recorder window.</p>

<p>With that in mind, let’s move on to the actual test. I’m going to record a bit of myself reading a book on both Zoom (locally) and my Rodecaster Pro interface (with audio processing turned off).</p>

<div align="center"><iframe width="560" height="315" src="https://www.youtube.com/embed/Z9Y1kLEqvOw" title="YouTube video player" frameborder="0" allow="accelerometer; autoplay; clipboard-write; encrypted-media; gyroscope; picture-in-picture" allowfullscreen=""></iframe></div>

<p>There’s certainly a difference between the two recordings, but I don’t think it’s particularly big. (I also realise that with the audio setup most podcast guests have, it won’t be noticeable at all). So, in my view, the answer to the main question of this post is — yes, it’s totally fine to record a podcast interview on Zoom if you know what you’re doing and are willing to jump through all the hoops.</p>

<p>As for the shows I’m working on with <a href="https://proceed.to">Proceed.to</a>, I can’t wait to put the “in-person interviews only” rule back in place.</p>]]></content><author><name>Andrii Degeler</name><email>shlema@gmail.com</email></author><summary type="html"><![CDATA[When I first took over the Tech.eu Podcast in 2018, one of the first decisions I made was that I’d only record interviews online in absolutely exceptional circumstances. Almost of my interviews from that and next year had been recorded in person, and there’s a whole bunch of reasons for that.]]></summary><media:thumbnail xmlns:media="http://search.yahoo.com/mrss/" url="https://shlema.me/assets/img/zoom-audio-test.jpg" /><media:content medium="image" url="https://shlema.me/assets/img/zoom-audio-test.jpg" xmlns:media="http://search.yahoo.com/mrss/" /></entry><entry><title type="html">Personal news time: I’m leaving Tech.eu</title><link href="https://shlema.me/leaving-tech-eu/" rel="alternate" type="text/html" title="Personal news time: I’m leaving Tech.eu" /><published>2021-11-01T00:00:00+01:00</published><updated>2021-11-01T00:00:00+01:00</updated><id>https://shlema.me/leaving-tech-eu</id><content type="html" xml:base="https://shlema.me/leaving-tech-eu/"><![CDATA[<p>So, long story short — it’s been a great three-year-long ride, but this coming Friday (November 5) is my last day at <a href="https://tech.eu">Tech.eu</a>. It’s a bittersweet feeling I’m leaving the company with, and I’m sure the recent <a href="https://tech.eu/home-featured/42474/webrazzi-acquisition/">acquisition by Webrazzi</a> will give Tech.eu a huge boost — but this is something I’ll be watching from the sideline.</p>

<p>I joined Tech.eu in 2018 as a news writer, but since then I feel like I’ve done nearly every possible job within the organisation, except maybe bookkeeping. I’ve hosted and produced our <a href="https://podcast.tech.eu">podcast show</a>, wrote reported features and sponsored content, sent out our newsletters, oversaw a major database migration project, did quite some coding in SQL and Python to leverage our proprietary funding data, represented Tech.eu at conferences online and offline, and did so much more. This was certainly one-of-a-kind opportunity to try a million of different things, and I’m happy I’ve seized it as well as I could.</p>

<p>For me, Tech.eu has been and will always be about the people, a collection of fun, bright, kind, and curious individuals whom I had a pleasure to encounter over the years. Huge thanks to Natalie, Mary, Helen, Annie, Piyush, Ana, Heini, Natasa, Dan — and, of course, Robin. I’ve had a great time working with you, I’ve learned a lot from you all, and I hope to stay in touch in the future.</p>

<p>As for what happens next, I’m fairly open to opportunities the future may hold. For the time being, I’m happy to take on projects related to podcasting, content strategy, writing, and so on — check out <a href="https://proceed.to">Proceed.to</a> to see what I, together with a trusted bunch of fellow freelancers, have got to offer.</p>

<p>If you’re reading this post around the time it’s published, there’s a big chance we’ll see each other at Web Summit. Don’t hesitate to come and say hi if you see me around, or ping me on <a href="https://twitter.com/adegeler">Twitter</a> to meet up!</p>

<p>So, here’s to the good old times — and exciting new beginnings.</p>]]></content><author><name>Andrii Degeler</name><email>shlema@gmail.com</email></author><summary type="html"><![CDATA[So, long story short — it’s been a great three-year-long ride, but this coming Friday (November 5) is my last day at Tech.eu. It’s a bittersweet feeling I’m leaving the company with, and I’m sure the recent acquisition by Webrazzi will give Tech.eu a huge boost — but this is something I’ll be watching from the sideline.]]></summary><media:thumbnail xmlns:media="http://search.yahoo.com/mrss/" url="https://shlema.me/assets/img/techeu_brussels.jpg" /><media:content medium="image" url="https://shlema.me/assets/img/techeu_brussels.jpg" xmlns:media="http://search.yahoo.com/mrss/" /></entry></feed>